BehaviorGPT-Commerce 1
Purchase and session sequences modeled as the language of consumption.
- Parameters
- 150M

One 12.5B-parameter model, pretrained on 150 billion user actions, evaluated on public benchmarks whose products and users it has never seen.
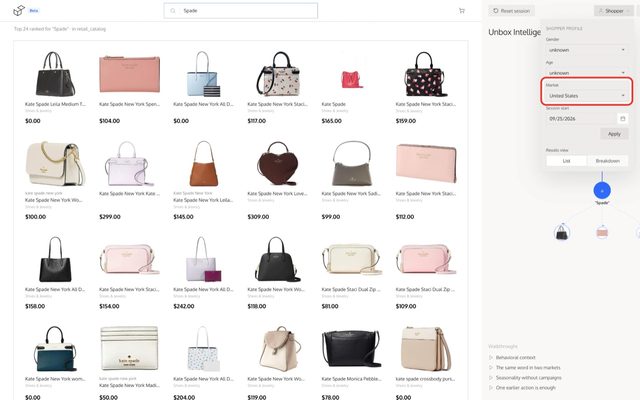
No training required. Fine-tuning is optional.
import unbox

client = unbox.UnboxAI(api_key="your_prod_key")

# the customer's live transaction from the auth stream
def authorize(event):

    # 1. Load the cardholder's transaction history
    user = client.history.load(user_id=event.card_hash)

    # 2. Score how likely this transaction is fraud
    result = client.score(history=user, action=event)

    # 3. Act on the Unbox intelligence score
    if result.probability > 0.95:
        return "DECLINED: BEHAVIORAL_ANOMALY"
return "APPROVED"import unbox
client = unbox.UnboxAI(api_key="your_prod_key")
# project a customer's value from their behavior
def lifetime_value(user_id):
# 1. Load the customer's full behavior history
user = client.history.load(user_id=user_id)
# 2. Predict expected value over the next 12 months
result = client.predict(history=user, target="clv_12m")
# 3. Act on the projected lifetime value
if result.value > 5000:
return "SEGMENT: HIGH_VALUE"
return "SEGMENT: STANDARD"
import unbox

client = unbox.UnboxAI(api_key="your_prod_key")

# assess default risk for a credit application
def underwrite(application):

    # 1. Load the applicant's behavior history
    user = client.history.load(user_id=application.user_id)

    # 2. Score the probability of default
    result = client.score(history=user, action=application)

    # 3. Act on the Unbox risk score
    if result.probability > 0.30:
        return "DECISION: DECLINE"
    return "DECISION: APPROVE"
import unbox

client = unbox.UnboxAI(api_key="your_prod_key")

# rank the next-best items for a live shopper
def recommend(session):

    # 1. Load the shopper's behavior history
    user = client.history.load(user_id=session.user_id)

    # 2. Rank the catalog by predicted intent
    result = client.rank(history=user, candidates=session.catalog)

    # 3. Return the top items to surface
    return result.top(k=10)
import unbox

client = unbox.UnboxAI(api_key="your_prod_key")

# re-rank search results by behavioral intent
def search(query, session):

    # 1. Load the user's behavior history
    user = client.history.load(user_id=session.user_id)

    # 2. Retrieve and rank results for the query
    result = client.search(history=user, query=query)

    # 3. Return the ranked results
    return result.top(k=20)
Purchase and session sequences modeled as the language of consumption.
Employee action sequences, predicting workforce dynamics from behavior rather than surveys.
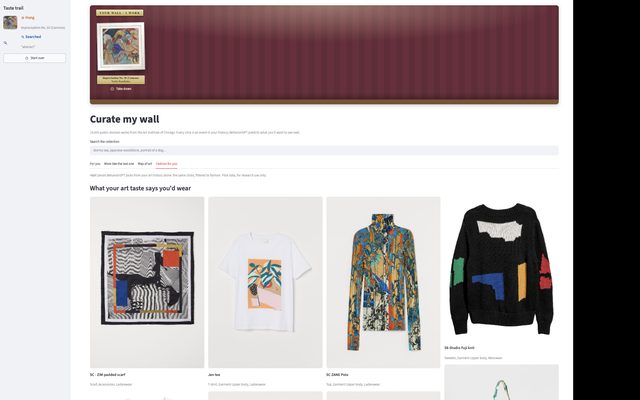
The second commerce generation, learning taste from what people do rather than from pixels.
One backbone unifying behavior across retail and payments, transferring zero-shot across domains.
BehaviorGPT is a foundation model for human behavior. It learns directly from sequences of actions such as purchases, searches, and clicks, with no hand-engineered features. One pretrained model transfers across catalogs, companies, and tasks.
A recommender scores items against a user profile or matches similar users. BehaviorGPT models the sequence itself, so earlier actions change how the next one is read. That context lets it identify intent instead of scoring each action in isolation.
Yes. The same action can be routine or suspicious depending on what preceded it, and BehaviorGPT models that sequence directly. It scores risk in real time as a session unfolds, and the model that powers recommendations adapts to fraud and risk without retraining from scratch.
Chronological event streams: transactions, searches, sessions, and interactions. No labels or engineered features are required.
Yes. Click Get API key, enter your work email, and your API key arrives by email together with a link to the demo and the example notebooks. Enterprise deployments are available separately.
Immediately. The key is emailed as soon as you sign up. It is shown only in that email, so keep it. If you sign up again with the same address we point you back to the original email.
Yes. Our papers and documentation are on the research page.
A purchase history is a sequence, so we trained on it the way a language model trains on text: next-event prediction over roughly 600M online actions and 15B offline grocery purchases. What comes out is a single representation of a shopper that search, recommendations, and assortment can all read from, with none of the manual tagging the incumbent tools depend on.
Nothing about the recipe is specific to shopping, so we pointed it at workforce actions instead: 43M events from 80,000 employees, with salted IDs, jittered timestamps, and per-person splits. The architecture and hyperparameters carried over from commerce unchanged, and pretraining on next-event prediction beat training the same model from scratch on attrition by 7%.
The second commerce generation: 0.5B parameters trained on 215B interactions, or 4.7T tokens, across major art and design platforms. Similarity here is defined by behavior rather than pixels: which motifs people view, search for, and buy together decides what counts as alike, and that behavioral notion of taste beat the specialist engines it was A/B tested against.
Details coming soon.
PaperLanguage modeling had two defining moments: a single pretrained model, fine-tuned per task, displaced the task-specific systems before it; then scale let it match or beat them on tasks and corpora it had never seen, with no adaptation at all. Behavioral data has had neither: despite being the dominant data asset of retail, engagement (app usage) and payments, behavior is still modeled one dataset, one task and one domain at a time, and every behavioral foundation model proposed so far is confined to the single event stream it was pretrained on and to that stream's own internal tasks. This is not intrinsic to behavior.
We present BehaviorGPT-v4, a single 12.5B-parameter Large Behavioral Model (LBM) trained by next-event prediction on 150 billion user actions (3.6 trillion tokens) as chronological sequences of discrete, multimodal events, a formulation that contains language modeling as a special case while retaining the ability to decide in a single step rather than token by token. Zero-shot, on public benchmarks whose catalogues and users it has never seen, it outperforms sequential, generative, transferable, tabular and LLM baselines trained on those datasets in full: none of them reaches our zero-shot accuracy at any data budget, light fine-tuning more than doubles it, and it learns from target data 17× faster than the strongest baseline. The same checkpoint, with no per-dataset architecture, objective or vocabulary changes, outperforms the strongest available specialist across three industries, 13 datasets and eight task surfaces: it leads all 29 dataset–surface pairs.
Generality is bought by scale: from our 0.5B checkpoint to our 12.5B, zero-shot transfer improves and the target data needed for a given accuracy falls. It ranks a whole catalogue in one forward pass, in under a millisecond, as cheaply as the lightest learned recommenders and 48× faster than a prompted LLM; in production A/B tests, our models increase sales by double-digit percentages against the incumbent commercial systems. We release an SDK and API that deploy any catalogue zero-shot, an evaluation harness, and live demos built on the SDK, and invite others to build their own.
Full paper coming soon.